Stefaan Verhulst
Paper by Chris Norval, Jennifer Cobbe and Jatinder Singh: “As the IoT becomes increasingly ubiquitous, concerns are being raised about how IoT systems are being built and deployed. Connected devices will generate vast quantities of data, which drive algorithmic systems and result in real-world consequences. Things will go wrong, and when they do, how do we identify what happened, why they happened, and who is responsible? Given the complexity of such systems, where do we even begin?
This chapter outlines aspects of accountability as they relate to IoT, in the context of the increasingly interconnected and data-driven nature of such systems. Specifically, we argue the urgent need for mechanisms – legal, technical, and organisational – that facilitate the review of IoT systems. Such mechanisms work to support accountability, by enabling the relevant stakeholders to better understand, assess, interrogate and challenge the connected environments that increasingly pervade our world….(More)”
Paper by Astha Kapoor: “… there is a need to think of exploitation on platforms not only through the lens of labour rights but also that of data rights. In the current context, it is impossible to imagine well-being without more agency on the way data are collected, stored and used. It is imperative to envision structures through which worker communities and representatives can be more involved in determining their own data lives on platforms. There is a need to organize and mobilize workers on data rights.
One of the ways in which this can be done is through a mechanism of community data stewards who represent the needs and interests of workers to their platforms, thus negotiating and navigating the data-based decisions. This paper examines the need for data rights as a critical requirement for worker well-being in the platform economy and the ways in which it can be actualized. It argues, given that workers on platforms produce data through collective labour on and off the platform, that worker data are a community resource and should be governed by representatives of workers who can negotiate with platforms on the use of that data for workers and for the public interest. The paper analyses the opportunity for a community data steward mechanism that represents workers’ interests and intermediates on data issues, such as transparency and accountability, with offline support systems. And is also a voice to online action to address some of the injustices of the data economy. Thus, a data steward is a tool through which workers better control their data—consent, privacy and rights—better and organize online. Essentially, it is a way forward for workers to mobilize collective bargaining on data rights.
The paper covers the impact of the COVID-19 pandemic on workers’ rights and well-being. It explores the idea of community data rights on the platform economy and why collective bargaining on data is imperative for any kind of meaningful negotiation with technology companies. The role of a community data steward in reclaiming workers’ power in the platform economy is explained, concluding with policy recommendations for a community data steward structure in the Indian context….(More)”.
Paper by Frank Hendriks: “Pushed by technological, cultural and related political drivers, a ‘new plebiscitary democracy’ is emerging which challenges established electoral democracy as well as variants of deliberative democracy. The new plebiscitary democracy reinvents and radicalizes longer-existing methods (initiative, referendum, recall, primary, petition, poll) with new tools and applications (mostly digital). It comes with a comparatively thin conceptualization of democracy, invoking the bare notion of a demos whose aggregated will is to steer actors and issues in public governance in a straight majoritarian way. In addition to unravelling the reinvented logic of plebiscitary democracy in conceptual terms, this article fleshes out an empirically informed matrix of emerging formats, distinguishing between votations that are ‘political-leader’ and ‘public-issue’ oriented on the one hand, and ‘inside-out’ and ‘outside-in’ initiated on the other hand. Relatedly, it proposes an agenda for systematic research into the various guises, drivers and implications of the new plebiscitary democracy. Finally, it reflects on possible objections to the argumentation….(More)”
Paper by Andrew M. Davis et al: “Collaborative efforts between public and private entities such as academic institutions, governments, and pharmaceutical companies form an integral part of scientific research, and notable instances of such initiatives have been created within the life science community. Several examples of alliances exist with the broad goal of collaborating toward scientific advancement and improved public welfare. Such collaborations can be essential in catalyzing breaking areas of science within high-risk or global public health strategies that may have otherwise not progressed. A common term used to describe these alliances is public-private partnership (PPP). This review discusses different aspects of such partnerships in drug discovery/development and provides example applications as well as successful case studies. Specific areas that are covered include PPPs for sharing compounds at various phases of the drug discovery process—from compound collections for hit identification to sharing clinical candidates. Instances of PPPs to support better data integration and build better machine learning models are also discussed. The review also provides examples of PPPs that address the gap in knowledge or resources among involved parties and advance drug discovery, especially in disease areas with unfulfilled and/or social needs, like neurological disorders, cancer, and neglected and rare diseases….(More)”.
Essay by Chantal Bernier: “Innovation feeds on data, both personal, identified data and de-identified data. To protect the data from increasing privacy risks, governance structures emerge to allow the use and sharing of data as necessary for innovation while addressing privacy risks. Two frameworks proposed to fulfill this purpose are data trusts and regulatory sandboxes.
The Government of Canada introduced the concept of “data trust” into the Canadian privacy law modernization discussion through Canada’s Digital Charter in Action: A Plan by Canadians, for Canadians, to “enable responsible innovation.” At a high level, a data trust may be defined, according to the Open Data Institute, as a legal structure that is appropriate to the data sharing it is meant to govern and that provides independent stewardship of data.
Bill C-11, known as the Digital Charter Implementation Act, 2020, and tabled on November 17, 2020, lays the groundwork for the possibility of creating data trusts for private organizations to disclose de-identified data to specific public institutions for “socially beneficial purposes.” In her recent article “Replacing Canada’s 20-Year-Old Data Protection Law,” Teresa Scassa provides a superb overview and analysis of the bill.
Another instrument for privacy protective innovation is referred to as the “regulatory sandbox.” The United Kingdom’s Information Commissioner’s Office (ICO) provides a regulatory sandbox service that encourages organizations to submit innovative initiatives without fear of enforcement action. From there, the ICO sandbox team provides advice related to privacy risks and how to embed privacy protection.
Both governance measures may hold the future of privacy and innovation, provided that we accept this equation: De-identified data may no longer be considered irrevocably anonymous and therefore should not be released unconditionally, but the risk of re-identification is so remote that the data may be released under a governance structure that mitigates the residual privacy risk.
Innovation Needs Identified Personal Data and De-identified Data
The role of data in innovation does not need to be explained. Innovation requires a full understanding of what is, to project toward what could be. The need for personal data, however, calls for far more than an explanation. Its use must be justified. Applications abound, and they may not be obvious to the layperson. Researchers and statisticians, however, underline the critical role of personal data with one word: reliability.
Processing data that can be traced, either through identifiers or through pseudonyms, allows superior machine learning, longitudinal studies and essential correlations, which provide, in turn, better data in which to ground innovation. Statistics Canada has developed a “Continuum of Microdata Access” to its databases on the premise that “researchers require access to microdata at the individual business, household or person level for research purposes. To preserve the privacy and confidentiality of respondents, and to encourage the use of microdata, Statistics Canada offers a wide range of options through a series of online channels, facilities and programs.”
Since the first national census in 1871, Canada has put data — derived from personal data collected through the census and surveys — to good use in the public and private sectors alike. Now, new privacy risks emerge, as the unprecedented volume of data collection and the power of analytics bring into question the notion that the de-identification of data — and therefore its anonymization — is irreversible.
And yet, data to inform innovation for the good of humanity cannot exclude data about humans. So, we must look to governance measures to release de-identified data for innovation in a privacy-protective manner. …(More)”.
Letter to the Editor of Nature by Vittoria Colizza et al: “Digital contact tracing is a public-health intervention. Real-time monitoring and evaluation of the effectiveness of app-based contact tracing is key for improvement and public trust.
SARS-CoV-2 is likely to become endemic in many parts of the world, and there is still no certainty about how quickly vaccination will become available or how long its protection will last. For the foreseeable future, most countries will rely on a combination of various measures, including vaccination, social distancing, mask wearing and contact tracing.
Digital contact tracing via smartphone apps was established as a new public-health intervention in many countries in 2020. Most of these apps are now at a stage at which they need to be evaluated as public-health tools. We present here five key epidemiological and public-health requirements for COVID-19 contact-tracing apps and their evaluation.
1. Integration with local health policy. App notifications should be consistent with local health policies. The app should be integrated into access to testing, medical care and advice on isolation, and should work in conjunction with conventional contact tracing where available1. Apps should be interoperable across countries, as envisaged by the European Commission’s eHealth Network.
2. High user uptake and adherence. Contact-tracing apps can reduce transmission at low levels of uptake, including for those without smartphones2. However, large numbers of users increase effectiveness3,4. An effective communication strategy that explains the apps’ role and addresses privacy concerns is essential for increasing adoption5. Design, implementation and deployment should make the apps accessible to harder-to-reach communities. Adherence to quarantine should be encouraged and supported.
3. Quarantine infectious people as accurately as possible. The purpose of contact tracing is to quarantine as many potentially infectious people as possible, but to minimize the time spent in quarantine by uninfected people. To achieve optimal performance, apps’ algorithms must be ‘tunable’, to adjust to the epidemic as it evolves6.
4. Rapid notification. The time between the onset of symptoms in an index case and the quarantine of their contacts is of key importance in COVID-19 contact tracing7,8. Where a design feature introduces a delay, it needs to be outweighed by gains in, for example, specificity, uptake or adherence. If the delays exceed the period during which most contacts transmit the disease, the app will fail to reduce transmission.
5. Ability to evaluate effectiveness transparently. The public must be provided with evidence that notifications are based on the best available data. The tracing algorithm should therefore be transparent, auditable, under oversight and subject to review. Aggregated data (not linked to individual people) are essential for evaluation of and improvement in the performance of the app. Data on local uptake at a sufficiently coarse-grained spatial resolution are equally key. As apps in Europe do not ‘geolocate’ people, this additional information can be provided by the user or through surveys. Real-time monitoring should be performed whenever possible….(More)”.
Thea Snow at LSE Blog: “Sometimes, you learn about an idea that really sticks with you. This happened to me recently when I learnt about “legibility” — a concept which James C Scott introduces in his book Seeing like a State.
Just last week, I was involved in two conversations which highlighted how pervasive the logic of legibility continues to be in influencing how governments think and act. But first, what is legibility?
Defining Legibility
Legibility describes the very human tendency to simplify complex systems in order to exert control over them.
In this blog, Venkatesh Rao offers a recipe for legibility:
- Look at a complex and confusing reality…
- Fail to understand all the subtleties of how the complex reality works
- Attribute that failure to the irrationality of what you are looking at, rather than your own limitations
- Come up with an idealized blank-slate vision of what that reality ought to look like
- Argue that the relative simplicity and platonic orderliness of the vision represents rationality
- Use power to impose that vision, by demolishing the old reality if necessary.
Rao explains: “The big mistake in this pattern of failure is projecting your subjective lack of comprehension onto the object you are looking at, as “irrationality.” We make this mistake because we are tempted by a desire for legibility.”
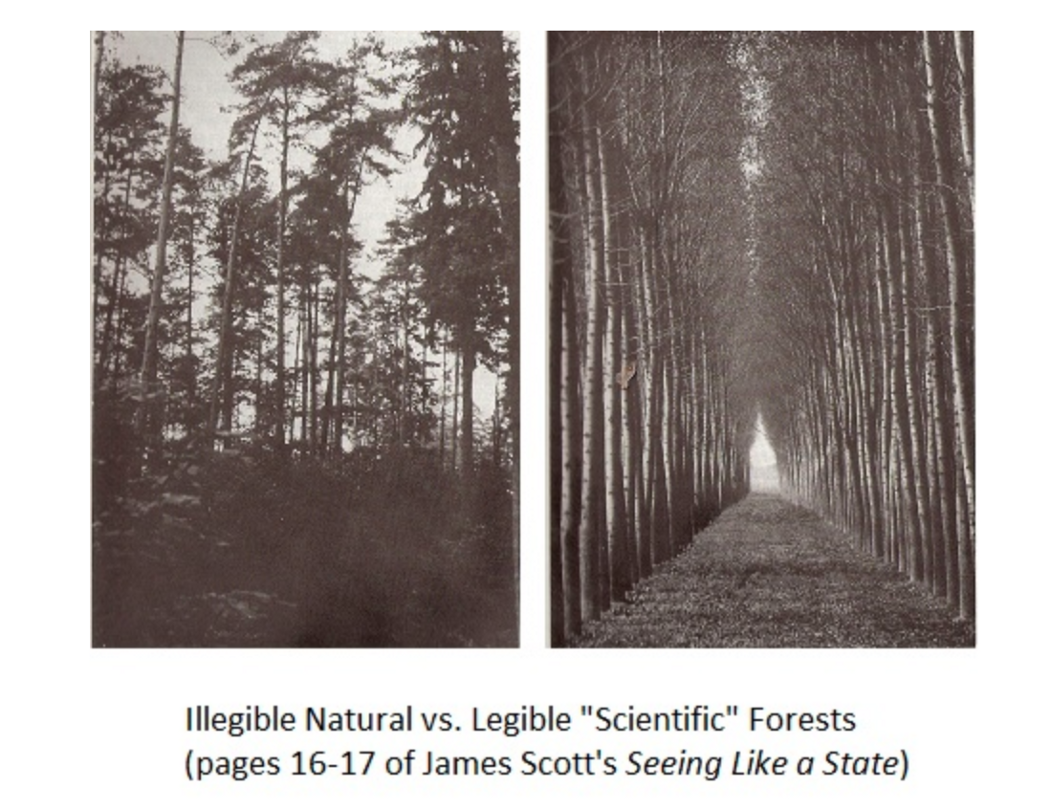
Scott uses modern forestry practices as an example of the practice of legibility. Hundreds of years ago, forests acted as many things — they were places people harvested wood, but also places where locals went foraging and hunting, as well as an ecosystem for animals and plants. According to the logic of scientific forestry practices, forests would be much more valuable if they just produced timber. To achieve this, they had to be made legible.
So, modern agriculturalists decided to clear cut forest, and plant perfectly straight rows of a particular species of fast-growing trees. It was assumed this would be more efficient. Planting just one species meant the quality of timber would be predictable. In addition, the straight rows would make it easy to know exactly how much timber was there, and would mean timber production could be easily monitored and controlled.
Reproduced from https://www.ribbonfarm.com/2010/07/26/a-big-little-idea-called-legibility/
For the first generation of trees, the agriculturalists achieved higher yields, and there was much celebration and self-congratulation. But, after about a century, the problems of the ecosystem collapse started to reveal themselves. In imposing a logic of order and control, scientific forestry destroyed the complex, invisible, and unknowable network of relationships between plants, animals and people, which are necessary for a forest to thrive.
After a century it became apparent that relationships between plants and animals were so distorted that pests were destroying crops. The nutrient balance of the soil was disrupted. And after the first generation of trees, the forest was not thriving at all….(More)”.
Paper by Angela Daly, S Kate Devitt, and Monique Mann: “In this chapter we argue that discourses on AI must transcend the language of ‘ethics’ and engage with power and political economy in order to constitute ‘Good Data’. In particular, we must move beyond the depoliticised language of ‘ethics’ currently deployed (Wagner 2018) in determining whether AI is ‘good’ given the limitations of ethics as a frame through which AI issues can be viewed. In order to circumvent these limits, we use instead the language and conceptualisation of ‘Good Data’, as a more expansive term to elucidate the values, rights and interests at stake when it comes to AI’s development and deployment, as well as that of other digital technologies.
Good Data considerations move beyond recurring themes of data protection/privacy and the FAT (fairness, transparency and accountability) movement to include explicit political economy critiques of power. Instead of yet more ethics principles (that tend to say the same or similar things anyway), we offer four ‘pillars’ on which Good Data AI can be built: community, rights, usability and politics. Overall we view AI’s ‘goodness’ as an explicly political (economy) question of power and one which is always related to the degree which AI is created and used to increase the wellbeing of society and especially to increase the power of the most marginalized and disenfranchised. We offer recommendations and remedies towards implementing ‘better’ approaches towards AI. Our strategies enable a different (but complementary) kind of evaluation of AI as part of the broader socio-technical systems in which AI is built and deployed….(More)”.
Paper by Adriano Koshiyama: “Business reliance on algorithms are becoming ubiquitous, and companies are increasingly concerned about their algorithms causing major financial or reputational damage. High-profile cases include VW’s Dieselgate scandal with fines worth of $34.69B, Knight Capital’s bankruptcy (~$450M) by a glitch in its algorithmic trading system, and Amazon’s AI recruiting tool being scrapped after showing bias against women. In response, governments are legislating and imposing bans, regulators fining companies, and the Judiciary discussing potentially making algorithms artificial “persons” in Law.
Soon there will be ‘billions’ of algorithms making decisions with minimal human intervention; from autonomous vehicles and finance, to medical treatment, employment, and legal decisions. Indeed, scaling to problems beyond the human is a major point of using such algorithms in the first place. As with Financial Audit, governments, business and society will require Algorithm Audit; formal assurance that algorithms are legal, ethical and safe. A new industry is envisaged: Auditing and Assurance of Algorithms (cf. Data privacy), with the remit to professionalize and industrialize AI, ML and associated algorithms.
The stakeholders range from those working on policy and regulation, to industry practitioners and developers. We also anticipate the nature and scope of the auditing levels and framework presented will inform those interested in systems of governance and compliance to regulation/standards. Our goal in this paper is to survey the key areas necessary to perform auditing and assurance, and instigate the debate in this novel area of research and practice….(More)”.
Paper by Paul Schmitt and Barath Raghavan: “To receive service in today’s cellular architecture, phones uniquely identify themselves to towers and thus to operators. This is now a cause of major privacy violations, as operators sell and leak identity and location data of hundreds of millions of mobile users. In this paper, we take an end-to-end perspective on the cellular architecture and find key points of decoupling that enable us to protect user identity and location privacy with no changes to physical infrastructure, no added latency, and no requirement of direct cooperation from existing operators. We describe Pretty Good Phone Privacy (PGPP) and demonstrate how our modified backend stack (NGC) works with real phones to provide ordinary yet privacy-preserving connectivity. We explore inherent privacy and efficiency tradeoffs in a simulation of a large metropolitan region. We show how PGPP maintains today’s control overheads while significantly improving user identity and location privacy…(More)”.