Stefaan Verhulst
Abeba Birhane at The Elephant: “The African equivalents of Silicon Valley’s tech start-ups can be found in every possible sphere of life around all corners of the continent—in “Sheba Valley” in Addis Abeba, “Yabacon Valley” in Lagos, and “Silicon Savannah” in Nairobi, to name a few—all pursuing “cutting-edge innovations” in sectors like banking, finance, healthcare, and education. They are headed by technologists and those in finance from both within and outside the continent who seemingly want to “solve” society’s problems, using data and AI to provide quick “solutions”. As a result, the attempt to “solve” social problems with technology is exactly where problems arise. Complex cultural, moral, and political problems that are inherently embedded in history and context are reduced to problems that can be measured and quantified—matters that can be “fixed” with the latest algorithm.
As dynamic and interactive human activities and processes are automated, they are inherently simplified to the engineers’ and tech corporations’ subjective notions of what they mean. The reduction of complex social problems to a matter that can be “solved” by technology also treats people as passive objects for manipulation. Humans, however, far from being passive objects, are active meaning-seekers embedded in dynamic social, cultural, and historical backgrounds.
The discourse around “data mining”, “abundance of data”, and “data-rich continent” shows the extent to which the individual behind each data point is disregarded. This muting of the individual—a person with fears, emotions, dreams, and hopes—is symptomatic of how little attention is given to matters such as people’s well-being and consent, which should be the primary concerns if the goal is indeed to “help” those in need. Furthermore, this discourse of “mining” people for data is reminiscent of the coloniser’s attitude that declares humans as raw material free for the taking. Complex cultural, moral, and political problems that are inherently embedded in history and context are reduced to problems that can be measured and quantified Data is necessarily always about something and never about an abstract entity.
The collection, analysis, and manipulation of data potentially entails monitoring, tracking, and surveilling people. This necessarily impacts people directly or indirectly whether it manifests as change in their insurance premiums or refusal of services. The erasure of the person behind each data point makes it easy to “manipulate behavior” or “nudge” users, often towards profitable outcomes for companies. Considerations around the wellbeing and welfare of the individual user, the long-term social impacts, and the unintended consequences of these systems on society’s most vulnerable are pushed aside, if they enter the equation at all. For companies that develop and deploy AI, at the top of the agenda is the collection of more data to develop profitable AI systems rather than the welfare of individual people or communities. This is most evident in the FinTech sector, one of the prominent digital markets in Africa. People’s digital footprints, from their interactions with others to how much they spend on their mobile top ups, are continually surveyed and monitored to form data for making loan assessments. Smartphone data from browsing history, likes, and locations is recorded forming the basis for a borrower’s creditworthiness.
Artificial Intelligence technologies that aid decision-making in the social sphere are, for the most part, developed and implemented by the private sector whose primary aim is to maximise profit. Protecting individual privacy rights and cultivating a fair society is therefore the least of their concerns, especially if such practice gets in the way of “mining” data, building predictive models, and pushing products to customers. As decision-making of social outcomes is handed over to predictive systems developed by profit-driven corporates, not only are we allowing our social concerns to be dictated by corporate incentives, we are also allowing moral questions to be dictated by corporate interest.
“Digital nudges”, behaviour modifications developed to suit commercial interests, are a prime example. As “nudging” mechanisms become the norm for “correcting” individuals’ behaviour, eating habits, or exercise routines, those developing predictive models are bestowed with the power to decide what “correct” is. In the process, individuals that do not fit our stereotypical ideas of a “fit body”, “good health”, and “good eating habits” end up being punished, outcast, and pushed further to the margins. When these models are imported as state-of-the-art technology that will save money and “leapfrog” the continent into development, Western values and ideals are enforced, either deliberately or intentionally….(More)”.
Nathan Heller at the New Yorker: “Imagine being a citizen of a diverse, wealthy, democratic nation filled with eager leaders. At least once a year—in autumn, say—it is your right and civic duty to go to the polls and vote. Imagine that, in your country, this act is held to be not just an important task but an essential one; the government was designed at every level on the premise of democratic choice. If nobody were to show up to vote on Election Day, the superstructure of the country would fall apart.
So you try to be responsible. You do your best to stay informed. When Election Day arrives, you make the choices that, as far as you can discern, are wisest for your nation. Then the results come with the morning news, and your heart sinks. In one race, the candidate you were most excited about, a reformer who promised to clean up a dysfunctional system, lost to the incumbent, who had an understanding with powerful organizations and ultra-wealthy donors. Another politician, whom you voted into office last time, has failed to deliver on her promises, instead making decisions in lockstep with her party and against the polls. She was reëlected, apparently with her party’s help. There is a notion, in your country, that the democratic structure guarantees a government by the people. And yet, when the votes are tallied, you feel that the process is set up to favor interests other than the people’s own.
What corrective routes are open? One might wish for pure direct democracy—no body of elected representatives, each citizen voting on every significant decision about policies, laws, and acts abroad. But this seems like a nightmare of majoritarian tyranny and procedural madness: How is anyone supposed to haggle about specifics and go through the dialogue that shapes constrained, durable laws? Another option is to focus on influencing the organizations and business interests that seem to shape political outcomes. But that approach, with its lobbyists making backroom deals, goes against the promise of democracy. Campaign-finance reform might clean up abuses. But it would do nothing to insure that a politician who ostensibly represents you will be receptive to hearing and acting on your thoughts….(More)”.
Paper by John W. Ayers et al: “There is widespread concern that the coronavirus disease 2019 (COVID-19) pandemic may harm population mental health, chiefly owing to anxiety about the disease and its societal fallout. But traditional population mental health surveillance (eg, telephone surveys, medical records) is time consuming, expensive, and may miss persons who do not participate or seek care. To evaluate the association of COVID-19 with anxiety on a population basis, we examined internet searches indicative of acute anxiety during the early stages of the COVID-19 pandemic.Methods
The analysis relied on nonidentifiable, aggregate, public data and was exempted by the University of California San Diego Human Research Protections Program. Acute anxiety, including colloquially called anxiety attacks or panic attacks, was monitored because of its higher prevalence relative to other mental health problems. It can lead to other mental health problems (including depression), it is triggered by outside stressors, and it is socially contagious. Using Google Trends (https://trends.google.com/trends) we monitored the daily fraction of all internet searches (thereby adjusting the results for any change in total queries) that included the terms anxiety or panic in combination with attack (including panic attack, signs of anxiety attack, anxiety attack symptoms) that originated from the US from January 1, 2004, through May 4, 2020. Raw search counts were inferred using Comscore estimates (comscore.com).
We compared search volumes after President Trump declared a national COVID-19 emergency on March 13, 2020, with expected search volumes if COVID-19 had not occurred, thereby taking into account the historical trend and periodicity in the data. Expected volumes were computed using an autoregressive integrated moving average model,4 based on historical trends from January 1, 2004 to March 12, 2020, to predict counterfactual trends for March 13, 2020 to May 9, 2020. The expected volumes with prediction intervals (PIs) and ratio of observed and expected volumes with bootstrap CIs were computed using R statistical software (version 3.5.3, R Foundation). The results were similar if we varied our interruption date plus or minus 1 week….(More)”.
Daniel Avelar at Open Democracy: “As Brazil faces one of the worst COVID-19 outbreaks in the world, a smartphone app is helping residents of impoverished areas known as favelas survive the virus threat amid sudden mass unemployment.
So far, the Latin American country has recorded over 115.000 deaths caused by COVID-19. The shutdown of economic activity wiped out 7.8 million jobs, mostly affecting low-skilled informal workers who form the bulk of the population in the favelas. Emergency income distributed by the government is limited to 60% of the minimum wage, so families are struggling to make ends meet.
Many blame president Jair Bolsonaro for the tragedy. Bolsonaro, a far-right populist, has consistently rallied against science-based policies in the management of the pandemic and pushed for an end to stay-at-home orders. A precocious reopening of the economy is likely to increase infection rates and cause more deaths.
In an attempt to stop the looming humanitarian catastrophe, a coalition of activists in the favelas and corporate partners developed an app that is facilitating the distribution of food and emergency income to thousands of women spearheading families. The app has a facial recognition feature that helps volunteers identify and register recipients of aid and prevents fraud.
So far, the Favela Mothers project has distributed the equivalent to US$ 26 million in food parcels and cash allowances to more than 1.1 million families in 5,000 neighborhoods across the country….(More)”.
Marietje Schaake at the Financial Times: “With a series of executive orders, US president Donald Trump has quickly changed the digital regulatory game. His administration has adopted unprecedented sanctions against the Chinese technology group Huawei; next on the list of likely targets is the Chinese ecommerce group Alibaba.
The TikTok takeover saga continues, since the president this month ordered the sale of its US operations within 90 days. The administration’s Clean Network programme also claims to protect privacy by keeping “unsafe” companies out of US cable, cloud and app infrastructure. Engaging with a shared privacy agenda, which the EU has enshrined in law, would be a constructive step.
Instead, US secretary of state Mike Pompeo has prioritised warnings about the dangers posed by Huawei to individual EU member states during a recent visit. Yet these unilateral American actions also highlight weaknesses in Europe’s own preparedness and unity on issues of national security in the digital world. Beyond emphasising fundamental rights and economic rules, Europe must move fast if it does not want to see other global actors draw the road maps of regulation.
Recent years have seen the acceleration of national security arguments to restrict market access for global technology companies. Decisions on bans and sanctions tend to rely on the type of executive power that the EU lacks, especially in the national security domain. The bloc has never fully developed a common security policy — and deliberately so. In its white paper on artificial intelligence, the European Commission explicitly omits AI in the military context, and European geopolitical clout remains underused by politicians keen to advance their national postures.
Tensions between the promise of a digital single market and the absence of a common approach to security were revealed in fragmented responses to 5G concerns, as well as foreign acquisitions of strategic tech companies. This ad hoc policy toolbox may well prove inadequate to build the co-ordination needed for a forceful European strategy. The US tussle with TikTok and Huawei should be a lesson to European politicians on their approach to regulating tech.
A confident Europe might argue that concerns about terabytes of the most intimate information being shared with foreign companies were promptly met with the EU’s general data protection regulations. A more critical voice would counter that Europe does not appreciate the risks of integrating Chinese tech into 5G networks, and that its narrow focus on fundamental rights and market regulations in the digital world was always naive.
Either way, now that geopolitics is integrating with tech policy, the EU risks being dethroned as the lead regulator of the digital world. In many ways it is remarkable that a reckoning took this long. For decades, online products and services have evaded restrictions on their reach into global communities. But the long-anticipated collision of geopolitics and technological disruption is finally here. It will do significant collateral damage to the open internet.
The challenge for democracies is to preserve their own core values and interests, along with the benefits of an open, global internet. A series of nationalistic bans and restrictions will not achieve these goals. Instead it will unleash a digital trade war at the expense of internet users worldwide..(More)”.
Book edited by Matthew L. Smith and Ruhiya Kristine Seward: “A decade ago, a significant trend in using and supporting open practices emerged in international development. “Open development” describes initiatives as wide-ranging as open government and data, open science, open education, and open innovation. The driving theory was that these types of open practices enable more inclusive processes of human development. This volume, drawing on ten years of empirical work and research, analyzes how open development has played out in practice.
Focusing on development practices in the Global South, the contributors assess the crucial questions of who is able to participate and benefit from open practices, and who cannot. Examining a wide range of cases, they offer a macro analysis of how open development ecosystems are governed, and evaluate the inclusiveness of a variety of applications, including creating open educational resources, collaborating in science and knowledge production, and crowdsourcing information….(More)”.
Paper by Jane Suiter, Lala Muradova, John Gastil and David M. Farrell: “This paper tests the possibility of embedding the benefits of minipublic deliberation within a wider voting public. We test whether a statement such as those derived from a Citizens’ Initiative Review (CIR) can influence voters who did not participate in the pre‐referendum minipublic deliberation. This experiment was implemented in advance of the 2018 Irish referendum on blasphemy, one of a series of social‐moral referendums following the recommendations of a deliberative assembly. This is the first application of a CIR‐style voting aid in a real world minipublic and referendum outside of the US and also the first application to what is principally a moral question. We found that survey respondents exposed to information about the minipublic and its findings significantly increased their policy knowledge. Further, exposing respondents to minipublic statements in favour and against the policy measure increased their empathy for the other side of the policy debate….(More)”.
Paper by Carson K. Leung et al: “As the urbanization of the world continues and the population of cities rise, the issue of how to effectively move all these people around the city becomes much more important. In order to use the limited space in a city most efficiently, many cities and their residents are increasingly looking towards public transportation as the solution. In this paper, we focus on the public bus system as the primary form of public transit. In particular, we examine open public transit data for the Canadian city of Winnipeg. We mine and conduct transportation analytics on data prior to the coronavirus disease 2019 (COVID-19) situation and during the COVID-19 situation. By discovering how often and when buses were reported to be too full to take on new passengers at bus stops, analysts can get an insight of which routes and destinations are the busiest. This information would help decision makers make appropriate actions (e.g., add extra bus for those busiest routines). This results in a better and more convenient transit system towards a smart city. Moreover, during the COVID-19 era, it leads to additional benefits of contributing to safer buses services and bus waiting experiences while maintaining social distancing…(More)”.
Open Corporates: “…there are three other aspects which are relevant when talking about access to EU company data.
Cargo-culting GDPR
The first, is a tendency to take this complex and subtle legislation that is GDPR and use a poorly understood version in other legislation and regulation, even if that regulation is already covered by GDPR. This actually undermines the GDPR regime, and prevents it from working effectively, and should strongly be resisted. In the tech world, such approaches are called ‘cargo-culting’.
Similarly GDPR is often used as an excuse for not releasing company information as open data, even when the same data is being sold to third parties apparently without concerns — if one is covered by GDPR, the other certainly should be.
Widened power asymmetries
The second issue is the unintended consequences of GDPR, specifically the way it increases asymmetries of power and agency. For example, something like the so-called Right To Be Forgotten takes very significant resources to implement, and so actually strengthens the position of the giant tech companies — for such companies, investing millions in large teams to decide who should and should not be given the Right To Be Forgotten is just a relatively small cost of doing business.
Another issue is the growth of a whole new industry dedicated to removing traces of people’s past from the internet (2), which is also increasing the asymmetries of power. The vast majority of people are not directors of companies, or beneficial owners, and it is only the relatively rich and powerful (including politicians and criminals) who can afford lawyers to stifle free speech, or remove parts of their past they would rather not be there, from business failures to associations with criminals.
OpenCorporates, for example, was threatened with a lawsuit from a member of one of the wealthiest families in Europe for reproducing a gazette notice from the Luxembourg official gazette (a publication that contains public notices). We refused to back down, believing we had a good case in law and in the public interest, and the other side gave up. But such so-called SLAPP suits are becoming increasingly common, although unlike many US states there are currently no defences in place to resist these in the EU, despite pressure from civil society to address this….
At the same time, the automatic assumption that all Personally Identifiable Information (PII), someone’s name for example, is private is highly problematic, confusing both citizens and policy makers, and further undermining democracies and fair societies. As an obvious case, it’s critical that we know the names of our elected representatives, and those in positions of power, otherwise we would have an opaque society where decisions are made by nameless individuals with opaque agendas and personal interests — such as a leader awarding a contract to their brother’s company, for example.
As the diagram below illustrates, there is some personally identifiable information that it’s strongly in the public interest to know. Take the director or beneficial owner of a company, for example, of course their details are PII — clearly you need to know their name (and other information too), otherwise what actually do you know about them, or the company (only that some unnamed individual has been given special protection under law to be shielded from the company’s debts and actions, and yet can benefit from its profits)?
On the other hand, much of the data which is truly about our privacy — the profiles, inferences and scores that companies store on us — is explicitly outside GDPR, if it doesn’t contain PII.
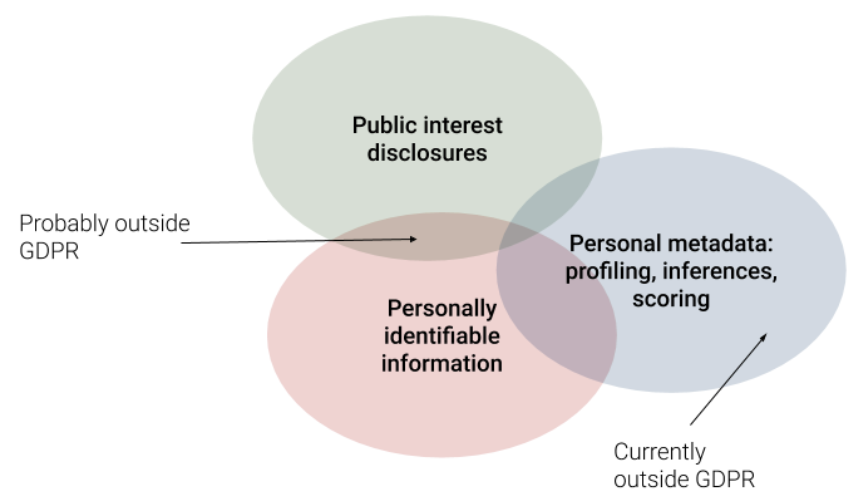
Hopefully, as awareness of the issues increases, we will develop a more nuanced, deeper, understanding of privacy, such that case law around GDPR, and successors to this legislation begin to rebalance and case law starts to bring clarity to the ambiguities of the GDPR….(More)”.
European Society of Cardiology: “Sending a “selfie” to the doctor could be a cheap and simple way of detecting heart disease, according to the authors of a new study published today (Friday) in the European Heart Journal [1].
The study is the first to show that it’s possible to use a deep learning computer algorithm to detect coronary artery disease (CAD) by analysing four photographs of a person’s face.
Although the algorithm needs to be developed further and tested in larger groups of people from different ethnic backgrounds, the researchers say it has the potential to be used as a screening tool that could identify possible heart disease in people in the general population or in high-risk groups, who could be referred for further clinical investigations.
“To our knowledge, this is the first work demonstrating that artificial intelligence can be used to analyse faces to detect heart disease. It is a step towards the development of a deep learning-based tool that could be used to assess the risk of heart disease, either in outpatient clinics or by means of patients taking ‘selfies’ to perform their own screening. This could guide further diagnostic testing or a clinical visit,” said Professor Zhe Zheng, who led the research and is vice director of the National Center for Cardiovascular Diseases and vice president of Fuwai Hospital, Chinese Academy of Medical Sciences and Peking Union Medical College, Beijing, People’s Republic of China.
He continued: “Our ultimate goal is to develop a self-reported application for high risk communities to assess heart disease risk in advance of visiting a clinic. This could be a cheap, simple and effective of identifying patients who need further investigation. However, the algorithm requires further refinement and external validation in other populations and ethnicities.”
It is known already that certain facial features are associated with an increased risk of heart disease. These include thinning or grey hair, wrinkles, ear lobe crease, xanthelasmata (small, yellow deposits of cholesterol underneath the skin, usually around the eyelids) and arcus corneae (fat and cholesterol deposits that appear as a hazy white, grey or blue opaque ring in the outer edges of the cornea). However, they are difficult for humans to use successfully to predict and quantify heart disease risk.
Prof. Zheng, Professor Xiang-Yang Ji, who is director of the Brain and Cognition Institute in the Department of Automation at Tsinghua University, Beijing, and other colleagues enrolled 5,796 patients from eight hospitals in China to the study between July 2017 and March 2019. The patients were undergoing imaging procedures to investigate their blood vessels, such as coronary angiography or coronary computed tomography angiography (CCTA). They were divided randomly into training (5,216 patients, 90%) or validation (580, 10%) groups.
Trained research nurses took four facial photos with digital cameras: one frontal, two profiles and one view of the top of the head. They also interviewed the patients to collect data on socioeconomic status, lifestyle and medical history. Radiologists reviewed the patients’ angiograms and assessed the degree of heart disease depending on how many blood vessels were narrowed by 50% or more (≥ 50% stenosis), and their location. This information was used to create, train and validate the deep learning algorithm….(More)”.