Stefaan Verhulst
Expert consensus report by Panayiota Kendeou, Jeffrey A. Greene, and Nia Nixon: “This report documents the findings and methodology of the consensus research project on Generative AI’s impact on learning in K-20 U.S. education. It is intended for researchers, educators, policymakers, and other stakeholders seeking evidence-based guidance.
Generative AI (GenAI) has been described as both the solution to humanity’s problems and also its greatest threat. In the context of education, those who look to research find mostly low-quality studies. Recent expert reports describe the risks of GenAI use but don’t tie them to specific learning processes. Experts in learning and education examined where GenAI helps learning, where it harms it, and what to do about it. They identified 65 learning processes GenAI can affect and rated how much GenAI could disrupt or enhance each one. Consensus was reached on 42 of the 65 processes…(More)”.
Essay by Niall Ferguson, Lisa Klaassen, and Eric Schmidt: “In the span of a few years, China and the United States have each assembled something future historians might recognize as a new kind of empire. Their dominions extend not merely over territory, trade routes, and airspace but over knowledge itself. By controlling the large language models, chips, physical infrastructure, and capital that provide the foundations for advanced machine cognition, Beijing and Washington are not only attaining new heights of economic performance and power projection; they are also setting the terms of all future scientific and intellectual progress. The term “AI superpowers” fails to capture the influence and reach that these rivals now wield. Even without active alliance building or coercion, they can make all other countries that seek access to advanced AI beholden to them.
Imperial history carries a warning. In the absence of other forces, empires seldom succumb to a challenger or to barbarians at the gates. More often, they fail because defending their vast dominions drains them dry, whether of material resources, the consent of the governed, or the loyalty of elites. The imperial center finds it can no longer maintain control over the periphery—the regions that once submitted to it. Failure can be financial, as it was for the British Empire after 1945, when the debts of two world wars forced London to liquidate its imperial assets to pay the price of victory: a welfare state for the citizens of the imperial metropole. It can be institutional, as it was for the Qing empire in the late nineteenth century, when it failed to industrialize, reform its bureaucracy, and renew the legitimacy of the Manchu dynasty.
Or it can be technological. The Royal Navy’s Dreadnought of 1906 gave the United Kingdom the first “all big gun” battleship and, with the same stroke, rendered its existing battle fleet obsolete. Overnight, this breakthrough opened the way for rivals such as Germany, erasing a century of accumulated British advantage. The resulting arms race forced the United Kingdom to nearly double naval spending between 1900 and 1914 and clashed with the Liberal government’s new social spending commitments, such as the Old Age Pension Act of 1908. The decisive question in the contest between Beijing and Washington may therefore not be who achieves artificial general intelligence first, but who can bankroll the race.
AI is imperial in two ways. On the one hand, China and the United States had empire-like qualities before the AI race began: Washington, the incumbent, pairs global military primacy with an alliance system no rival can match. It also supplies the currency for the lion’s share of international trade and transactions. Beijing, often described as the challenger, combines industrial and supply chain dominance with the world’s largest navy and a tightening grip on the physical and digital infrastructure of countries across Africa, Asia, and Latin America. For both, AI is a way to extend the power they already wield. But AI is also by its nature an imperial substance. Whoever produces and controls frontier models acquires global leverage over innovation, production, science, culture, and, ultimately, advanced thought. Much as silver underwrote Habsburg Spain and oil defined the “American century,” this new commodity will not merely enrich the powers that dominate it but also provide the basic operating system on which everyone else must depend…(More)”.
About: “V-Dem provides a multidimensional and disaggregated dataset that reflects the complexity of the concept of democracy as a system of rule that goes beyond the simple presence of elections. We distinguish between five high-level principles of democracy: electoral, liberal, participatory, deliberative, and egalitarian, and collect data to measure these principles.
The V-Dem Dataset – Includes the world’s most comprehensive and detailed democracy ratings. The latest version of the dataset and associated reference documents can be downloaded free of charge. Download the data – Each ZIP includes: Dataset, Codebook, What’s New, Cautionary Notes, and Suggested Citations. Download our datasets and reference materials…(More)”.
Article by Erik Brynjolfsson, Anton Korinek, and Ajay Agrawal: “AI has improved radically in recent years and is poised to become more powerful. Our institutions, organizations, skills, and economic models are struggling to keep pace. In this growing gap lie the greatest risks and challenges of the coming decade, as well as the greatest opportunities. We urgently need to improve our understanding of AI’s economic implications.
Key Insights
- Transformative AI (TAI) is advancing faster than our economic institutions can adapt, creating both unprecedented opportunities and significant risks that demand immediate attention.
- The implications of TAI are affecting almost all areas of economics and are posing fundamental questions about economic growth, science and innovation, income distribution, decision-making power, geoeconomics, information and knowledge, safety risks, and even our sense of meaning and worth.
- In this rapid transitional period, interdisciplinary collaboration between economists, computer scientists, and policymakers is crucial for developing the tools needed to align TAI with human well-being and prevent exacerbation of existing inequalities.
- Traditional productivity measures and GDP miss AI’s full economic impact. New economic measures must be developed to understand and prepare for a rapidly changing and fundamentally different economy.
Before we can formulate effective solutions, we must define the fundamental questions, laying the groundwork for a productive research agenda. By doing so, we seek to catalyze the insights and analytical tools necessary to navigate AI’s evolving landscape while fostering shared prosperity. A question well-posed is half answered…(More)”.
Article by Danai Nesta Kupemba: “Big Tech’s newest personal agents — Meta’s Muse and OpenAI’s Dots — promise to book tables at restaurants, buy groceries, and carry out other types of digital grunt work for users.
Consumers are opting in. Muse has been downloaded 9 million times in the U.S. and Canada since its launch on September 8, market intelligence company AppMagic, told Rest of World. As many as 1.8 million people use the app daily.
Meta aspires to a global launch. “[We] are quite excited to bring personal agents to billions of people around the world,” Alexandr Wang, Meta’s chief AI officer, told the Financial Times.
Some startups are already building agents in markets that Big Tech hopes to reach. For instance, South African startup ManyHands offers Manny, a personal assistant designed to order groceries, book appointments and make payments through WhatsApp. But adapting agents to local conditions has its challenges. Anton Moulder, ManyHands’ founder, told Rest of World that getting the AI assistant to converse in all of South Africa’s 11 official spoken languages has been difficult.
Rest of World spoke to AI researchers and other experts to understand how these personal agents would perform outside Western nations.
Would AI agents understand the local language and culture?
English speakers could benefit more from AI agents, which run on top of large language models that underperform in many non-English languages.
“Linguistic inclusion is ultimately about power,” Payal Arora, professor of inclusive AI cultures at Utrecht University and the founder of Inclusive AI Lab, told Rest of World.
Meta has said that expanding Muse internationally would require support for local languages and integration with local services.
AI agents would also need to understand the local culture, including the unique ways people communicate and bargain. “In many parts of the Global South, meaning is deeply contextual, shaped by family, community, religion, local institutions, and informal social networks,” Arora said.
Without that understanding, agents might impose Western assumptions on their users, Usha Raman, an independent researcher on AI policy and digital culture, told Rest of World. “The danger then is that existing forms of cultural and economic hegemony continue and the rest of the world is forced to adapt,” she said…(More)”.
Press Release: “Today, during the Committee on World Food Security, leaders from governments, UN agencies, technology companies, NGOs, philanthropies, and financial institutions announced the Intentional Data Community for Food and Nutrition Security (IDC), a new multi-stakeholder initiative to strengthen and connect the data systems used to anticipate, prevent, and respond to food and nutrition crises. The IDC will work to protect and strengthen critical data systems, increase investment in locally owned data collection and analysis, and better connect data to decisions and financing so governments and communities can act before crises hit.
The effort comes as funding for food and nutrition security data systems is declining even as conflict, climate, and economic shocks increase pressure on vulnerable communities. A powerful El Niño and disruptions in the Strait of Hormuz are adding to risks facing food, fuel, and fertilizer markets — underscoring the need for reliable early warning and risk monitoring and the ability to act on them.
New analysis undertaken by IFPRI as part of the VITAL Data initiative shows that funding to priority data systems was cut by an average of 31% in 2025. This includes cuts to FEWS NET, the Integrated Food Security Phase Classification (IPC), and, crucially, the household surveys on which they rely. During the launch event, leaders highlighted the consequences: a reduced ability to reliably understand rising risks; track the severity of malnutrition, famine and hunger; target food, nutrition, and other needed assistance; and help farmers, communities and governments take anticipatory action ahead of shocks, including floods and drought.
“The world has extraordinary tools to anticipate food crises, but those tools only work if we invest in the data and put it in the hands of people who can act,” said Simon Winter, Vice President of the Reimagining Humanitarian and Nutrition Security team at The Rockefeller Foundation’s public charity, RF Catalytic Capital. “As funding declines and El Niño threatens communities around the world, we need to protect and improve needed early warning and data systems and help local and national leaders use better information to act earlier, save lives, and protect livelihoods.”
“The cost of good data is small compared to the cost of responding too late. By strengthening food security information systems, the IDC can help governments and partners act earlier, target assistance better, and protect more lives. As the leading source of information on acute food insecurity, we know that timely and accurate data can be lifesaving for vulnerable communities everywhere” — Jean-Martin Bauer, Director, Food Security and Nutrition Analysis, World Food Programme…(More)”
Article by Sam Freedman: “LLMs have become so pervasive in our lives that it is easy to forget how new they are. ChatGPT was launched in November 2022, and by May this year 63% of the British population had used it or a competitor. Compare this to take-up of the internet: five years after the public launch of the World Wide Web, just 9% of households had access.
The speed with which LLMs have become familiar and their ability to produce reams of serviceable text has led to rapid, large-scale shifts in behaviour that are overwhelming institutions unable to adapt quickly enough.
Universities are an obvious example: most had shifted to coursework-based examinations just before LLMs made cheating far easier. But the explosion of near-instantaneous text is causing problems everywhere. Employers face a tsunami of AI-generated job applications to be waded through, literary agents are bombarded with AI manuscripts, and complaints departments find themselves overwhelmed.
Government has the biggest problem. Modern administrative states are built around processes that are difficult to use, often deliberately so, which helps ration demand. Regulatory and legal routes are designed on the assumption that only a small number of people who might use them actually will. AI blows this assumption apart. The chart below shows twelve different government services from around the world and the surge in applications/complaints received – the grey line shows when ChatGPT was launched.
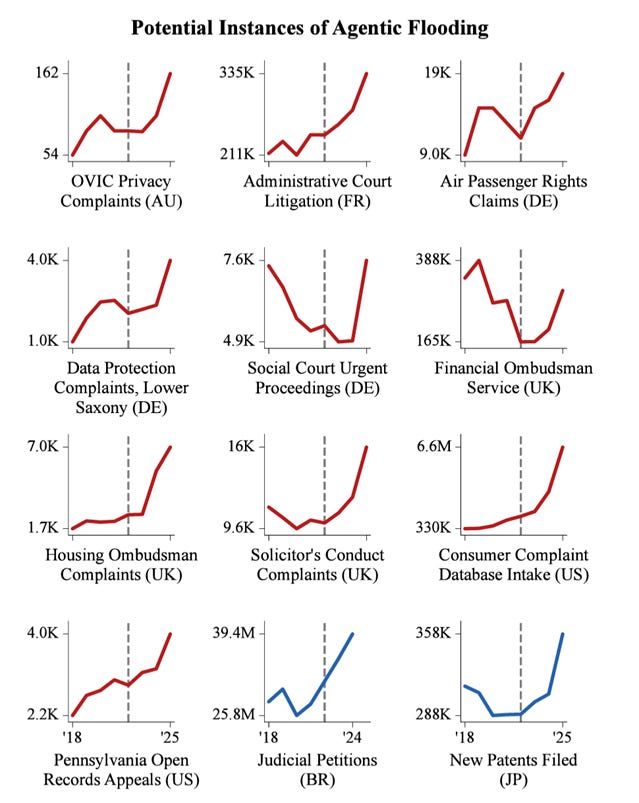
LLMs may not be the only reason for the rises, but are clearly playing an important role. One classification of requests to Google’s Gemini LLM finds that 1% are related to government interactions. That doesn’t sound like much until you realise that is around 2 billion a year for just one LLM. ChatGPT and Claude are more widely used.
The UK is particularly badly set up to deal with this, as we have an extremely centralised administrative state that is heavily dependent on national regulators and tribunals that can be quickly overwhelmed, and what local government we have is seriously under-resourced. In August, The Economist wrote about employment tribunals, which saw a 39% increase in people filing complaints against employers in the year to March. The backlog has shot up and hearings are now being listed to be heard in 2029, harming both unfairly treated employees and businesses. This is being repeated across government agencies…(More)”.
Article by Andrew Zolli: “Of all the questions we ask of a map, perhaps none is more fundamental than this one: Where are the people?
It sounds like a question we should have answered long ago. Yet in an age of seemingly ubiquitous, real-time information, our picture of where humanity actually lives remains surprisingly blurry. Censuses are expensive, infrequent and, in many places, badly out of date. Cities across the Global South are growing far faster than their residents can be counted. Conflict, disaster, and climate stress are setting millions of people in motion. The result is that many of the world’s most vulnerable communities are, in effect, invisible – and on a volatile, warming planet, invisibility can be fatal.
In early 2024, we announced a collaboration with the Institute for Health Metrics and Evaluation (IHME) at the University of Washington and Microsoft’s AI for Good Lab to help close that gap. Today, I’m delighted to share that the results of this multi-year initiative are being made widely available.
The result is Populace: a continuously updated map of the world’s population, realized in unprecedented detail. Populace measures the density of human populations across the entire globe at a gridded resolution of 40 meters, updated quarterly. It is the most up-to-date, highest resolution, and most accurate population data available anywhere – and it’s available now…(More)”.
Report by Trevor Potts: “Artificial Intelligence (AI) is rapidly reshaping how governments gather evidence, analyze information, and make decisions. In recent years, the Government of Canada has rapidly deployed new AI technologies and tools across the federal public service. While new technologies ostensibly promise improved efficiency and productivity, their deployment hasraised serious questions around perceived lack of transparency, gaps in regulation, implementation challenges, and potential for misuse and biased decision-making.
This project aims to explore how AI is reshaping evidence usage in the federal public service, and the implications AI usage has on federal policymaking and public trust in Canadian democracy…(More)”.
Article by Matt Prewitt and Salomé Viljoen: “AI companies’ need for large tracts of land has, for the first time, given communities a real public forum to push back against Big Tech. But stopping data centers won’t be enough. We must now extend the politics this moment has unleashed and give communities greater power over the future of a technology that will transform them.
AI models inherently concentrate power. They draw information from people and communities everywhere, and give their wielders power to fragment, shape, and manipulate those same communities. They are becoming extraordinarily powerful. Even if they aren’t existentially dangerous, they are not a “normal technology”.
Lawmakers must therefore do their job and regulate AI. A full response to AI’s harms will likely include a range of proposals. We believe one essential component of AI regulation is to move past interventions aimed at harm reduction to mechanisms of redistributing power over setting and directing AI’s future. In a new proposal, we argue for creating a new class of rights governing data use and collection, which makes associations — inspired by the historical structure of guilds, unions, and cooperatives — the wielders of a new class of data rights. These data associations can become the critical counterparties with whom tech companies must negotiate to build their powerful new technologies. We call this approach “associational data rights”.
This proposal aims not at “what” to fix about AI, but “who” to empower over the direction AI development takes. Our proposal creates new legal interests in data, which individuals exercise by assigning them to voluntary, member-governed associations. These associations would then work for their interests on their behalf. Large technology companies would have to negotiate with one or several of these associations in order to get rights to use data, or avoid serious liability.
Central to these new rights is the idea that individuals should be allowed to join and form a new type of special non-stock organization called a Data Rights Association (DRA). Being a member of a DRA would communicate to technology companies that certain rights concerning your data — the right to reasonable privacy, the right to a say in how the information is used, and the right to a fair share of the economic benefits — have been assigned to the DRA as your proxy. Companies would not be allowed to discriminate against DRA members in their service provision, or require terms of service that preclude DRA membership. In a nutshell, companies seeking to use customer data at scale would need to come to terms with a handful of consumer-side organizations with real bargaining power, instead of imposing lopsided terms on divided-and-conquered individuals…(More)”.